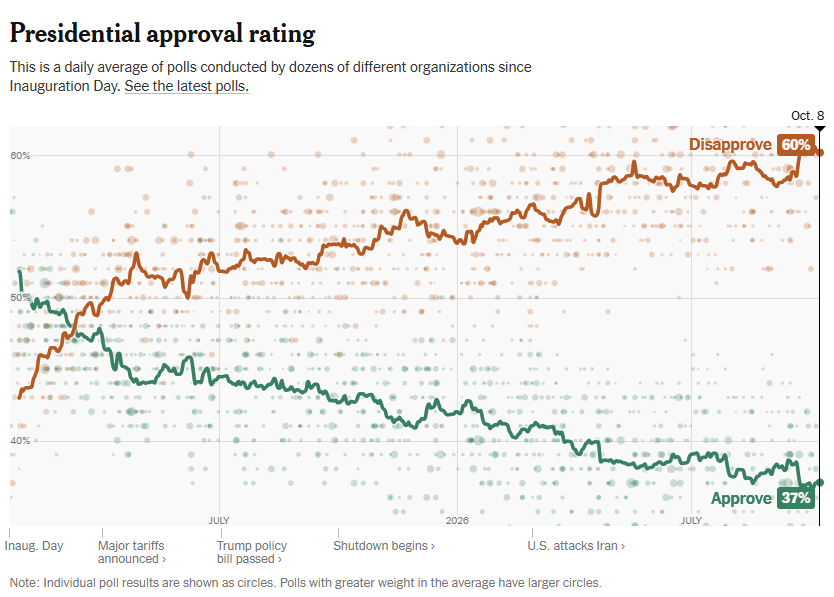
As of today, October 8, 2026, the New York Times’ presidential approval graphic labels approval of Trump at 37% and disapproval at 60%.
I can’t be sure of how they weight the polls, how they exclude outliers, etc., nor whether their “current” value actually represents a rolling aggregation centered on a past date — but it seems to me that the labels have a non-negligible delay. The median of the 10 latest “select” polls shown in the list is 33% approval and 63% disapproval — a net disapproval of 30 percentage points, 7 percentage points more than the 23 percentage points that their graphic suggests.
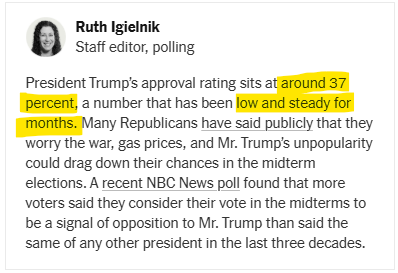
The second issue is the accompanying text, which says that the approval rating has been “low and steady for months.”
I would change steady to gradually declining.
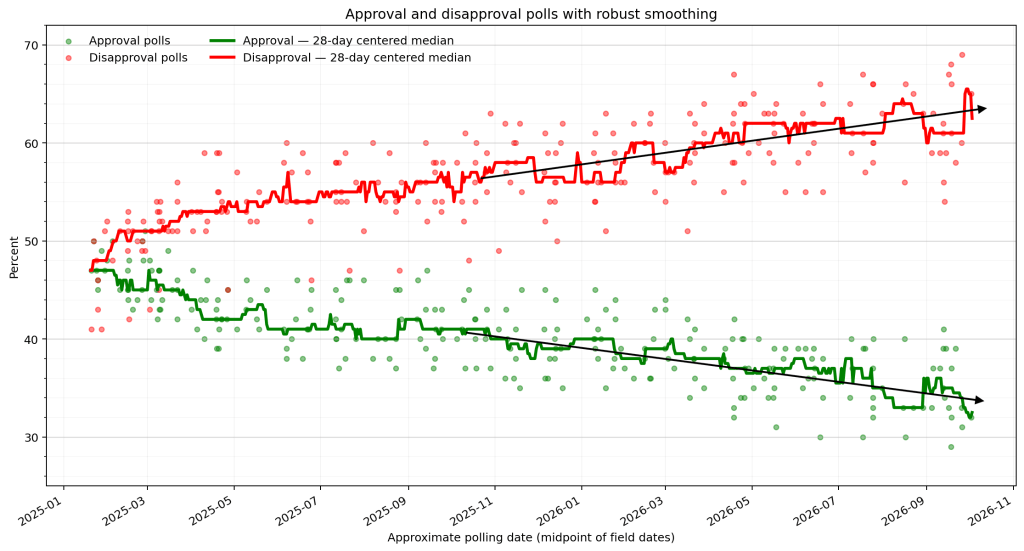
Looking at the “select” (quality) polls from November 1, 2025 onward, a robust Theil–Sen trend gives an approval decline of 0.55 percentage point per month and a disapproval increase of 0.57 percentage point per month. The fitted values move from roughly 41.1% approval and 56.8% disapproval at the beginning of November to about 35.0% approval and 63.2% disapproval by the latest polling dates. For months, the net disapproval has been increasing by slightly more than 1 percentage point per month: it is not steady, it is gradually increasing.
Besides, I would not use low for such approval numbers. I find approval in this range grotesquely high for the most incompetent leader the US has ever had, a pathological narcissist incapable of empathy or sympathy for anyone but himself in the country he is supposed to lead, who will break every single promise his supporters stupidly believed.
Note: data analysis of 248 “select” polls listed by the New York Times from Jan. 20–21, 2025 until Sept. 30–Oct. 5, 2026. Red and green lines show 28-day centered rolling median. Theil–Sen linear trends of the approval and disapproval are not shown — the black arrows are visual approximations.
The Météo-France hourly observations show ten consecutive days with maximum temperatures above 35°C at both Paris-Luxembourg and Paris-Montsouris, from June 18 to June 27, 2026. Paris-Luxembourg reached 42.1°C and accumulated 36.9 °C·days above 35°C, compared with 40.5°C and 24.6 °C·days at Paris-Montsouris. The nighttime burden was also greater at Luxembourg: 41.9 °C·nights above 20°C, versus 34.2 at Montsouris.
August 2003 comparison period
For comparison, the same script was run on Météo-France daily observations for July 25 to August 20, 2003.
Paris-Montsouris
Metric
August 2003
June 2026
Days above 35°C
9
10
Longest run above 35°C
9 days
10 days
Run start
2003-08-04
2026-06-18
Run end
2003-08-12
2026-06-27
Daytime excess above 35°C
28.1 °C·days
24.6 °C·days
Night excess above 20°C
35.0 °C·nights
34.2 °C·nights
Highest Tmax
39.5°C
40.5°C
Highest Tmin
25.5°C
26.6°C
Paris-Luxembourg
Metric
August 2003
June 2026
Days above 35°C
10
10
Longest run above 35°C
10 days
10 days
Run start
2003-08-03
2026-06-18
Run end
2003-08-12
2026-06-27
Daytime excess above 35°C
36.0 °C·days
36.9 °C·days
Night excess above 20°C
19.0 °C·nights
41.9 °C·nights
Highest Tmax
40.2°C
42.1°C
Highest Tmin
23.2°C
28.4°C
Comparing June 2026 with August 2003
At Paris-Montsouris, the June 2026 episode lasted ten consecutive days above 35°C, one day longer than the nine-day sequence from August 4 to August 12, 2003. Its peak was also higher, 40.5°C versus 39.5°C, but its cumulative daytime excess remained lower: 24.6 °C·days in 2026 versus 28.1 in the 2003 comparison window. The nighttime excess was similar but slightly lower in 2026, at 34.2 versus 35.0 °C·nights.
At Paris-Luxembourg, the 2026 heat wave matched the ten-day 2003 sequence. Its peak temperature was higher, 42.1°C versus 40.2°C, and both cumulative excess measures were also higher: 36.9 versus 36.0 °C·days during the day, and 41.9 versus 19.0 °C·nights at night.
Conclusion
The completed observations place the June 2026 heat wave in the same range as August 2003 by duration, with ten consecutive days above 35°C at both ground-level Paris stations. In central Paris, represented by Paris-Luxembourg, 2026 exceeded the 2003 comparison in peak temperature and nighttime heat burden. At Paris-Montsouris, however, August 2003 still produced the greater cumulative daytime excess despite its slightly shorter run. The comparison therefore does not yield a single citywide "winner": June 2026 was exceptionally long and intense in the urban core, while the severity of 2003 remained more pronounced at Montsouris by cumulative daytime excess.
I’ve done some crawling and data visualization, with the help of Codex.
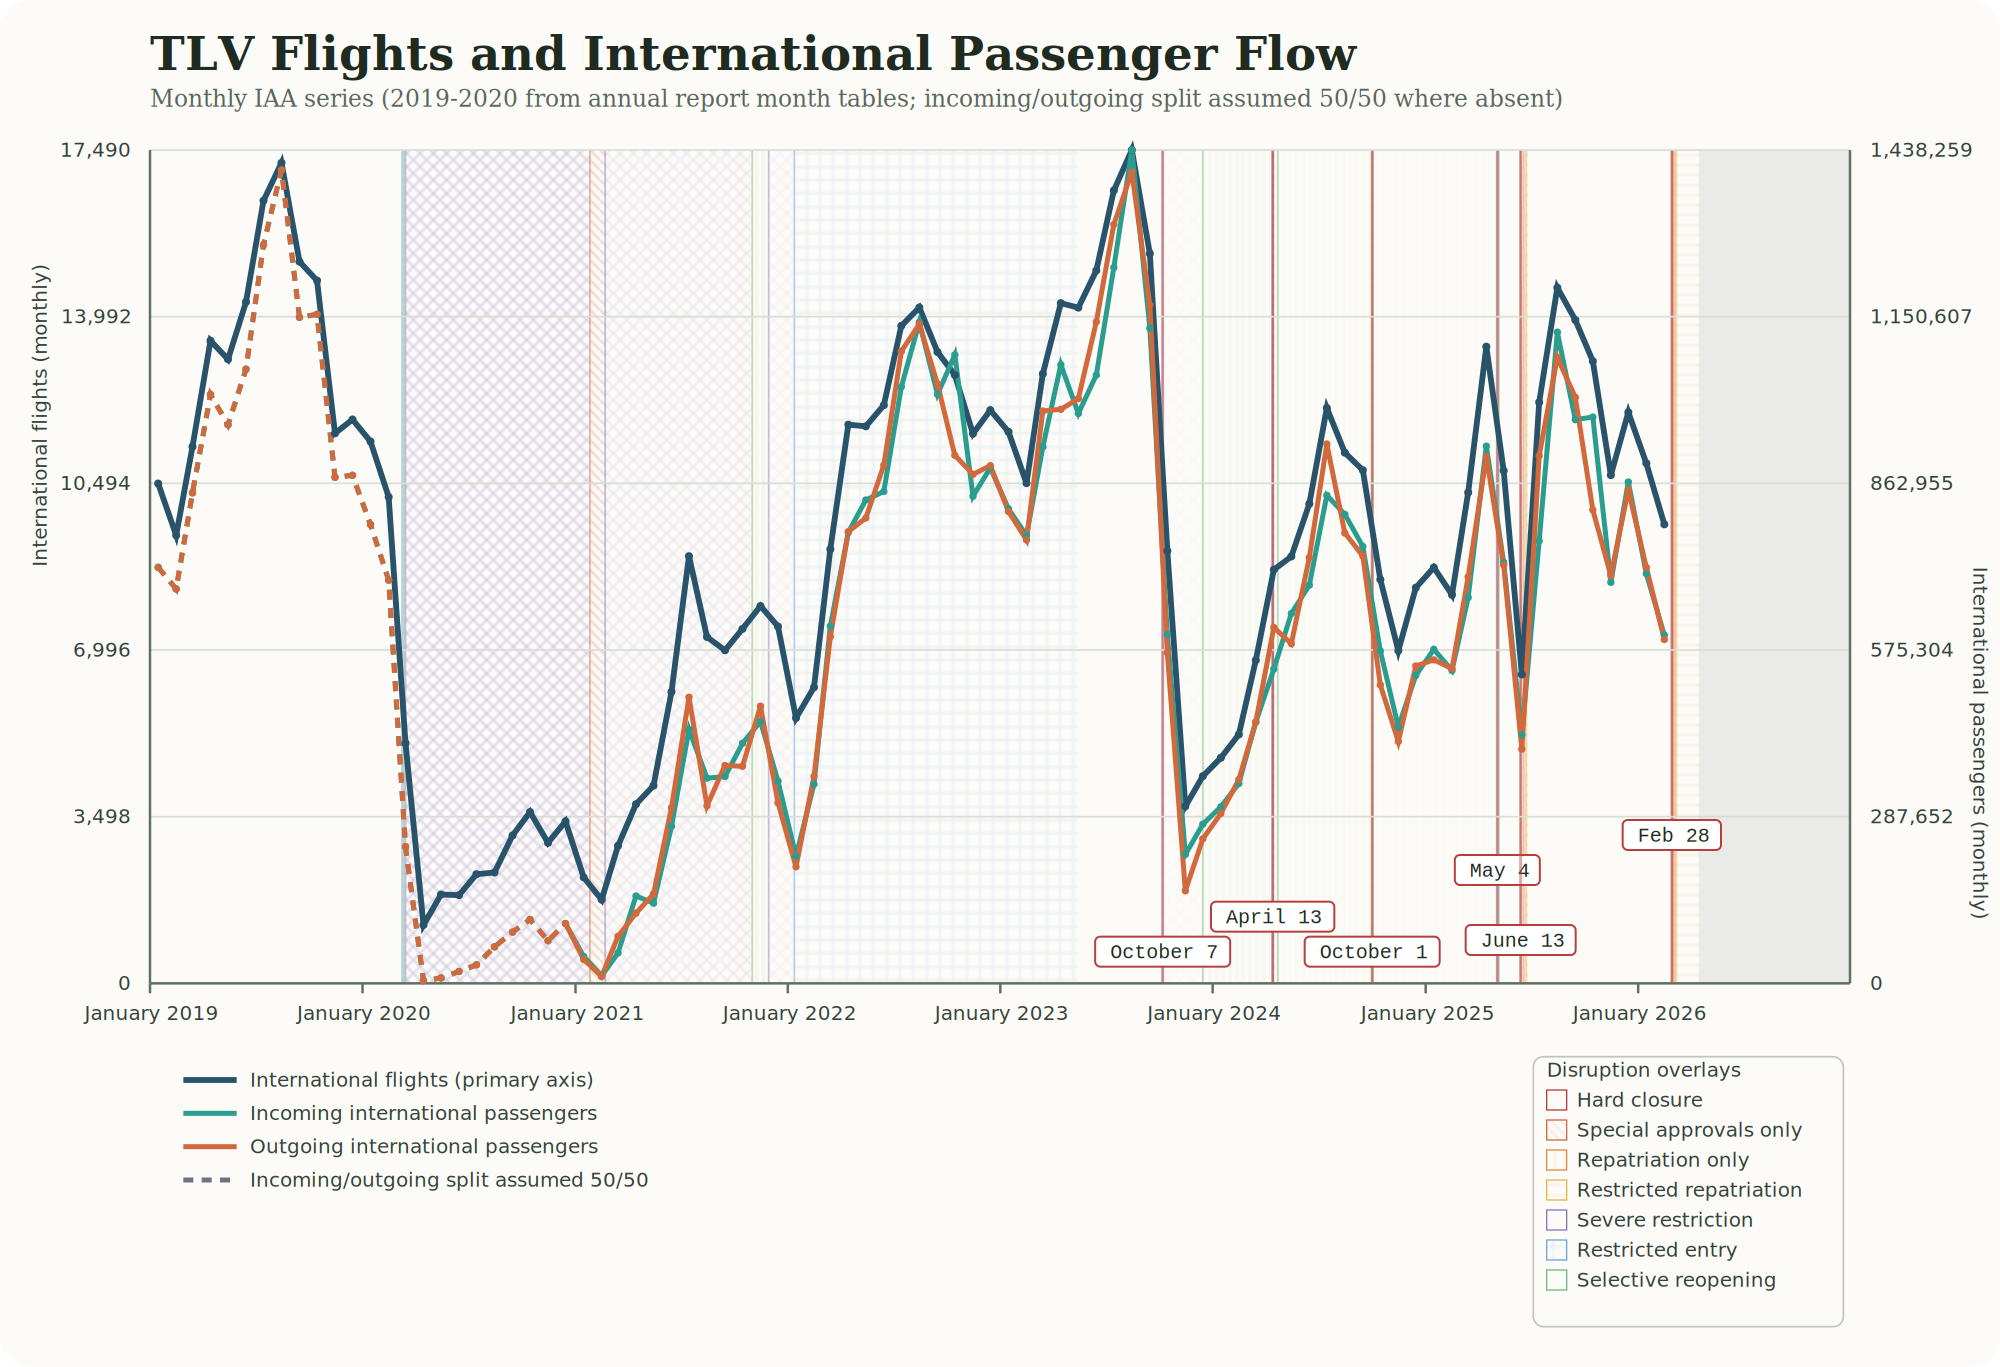
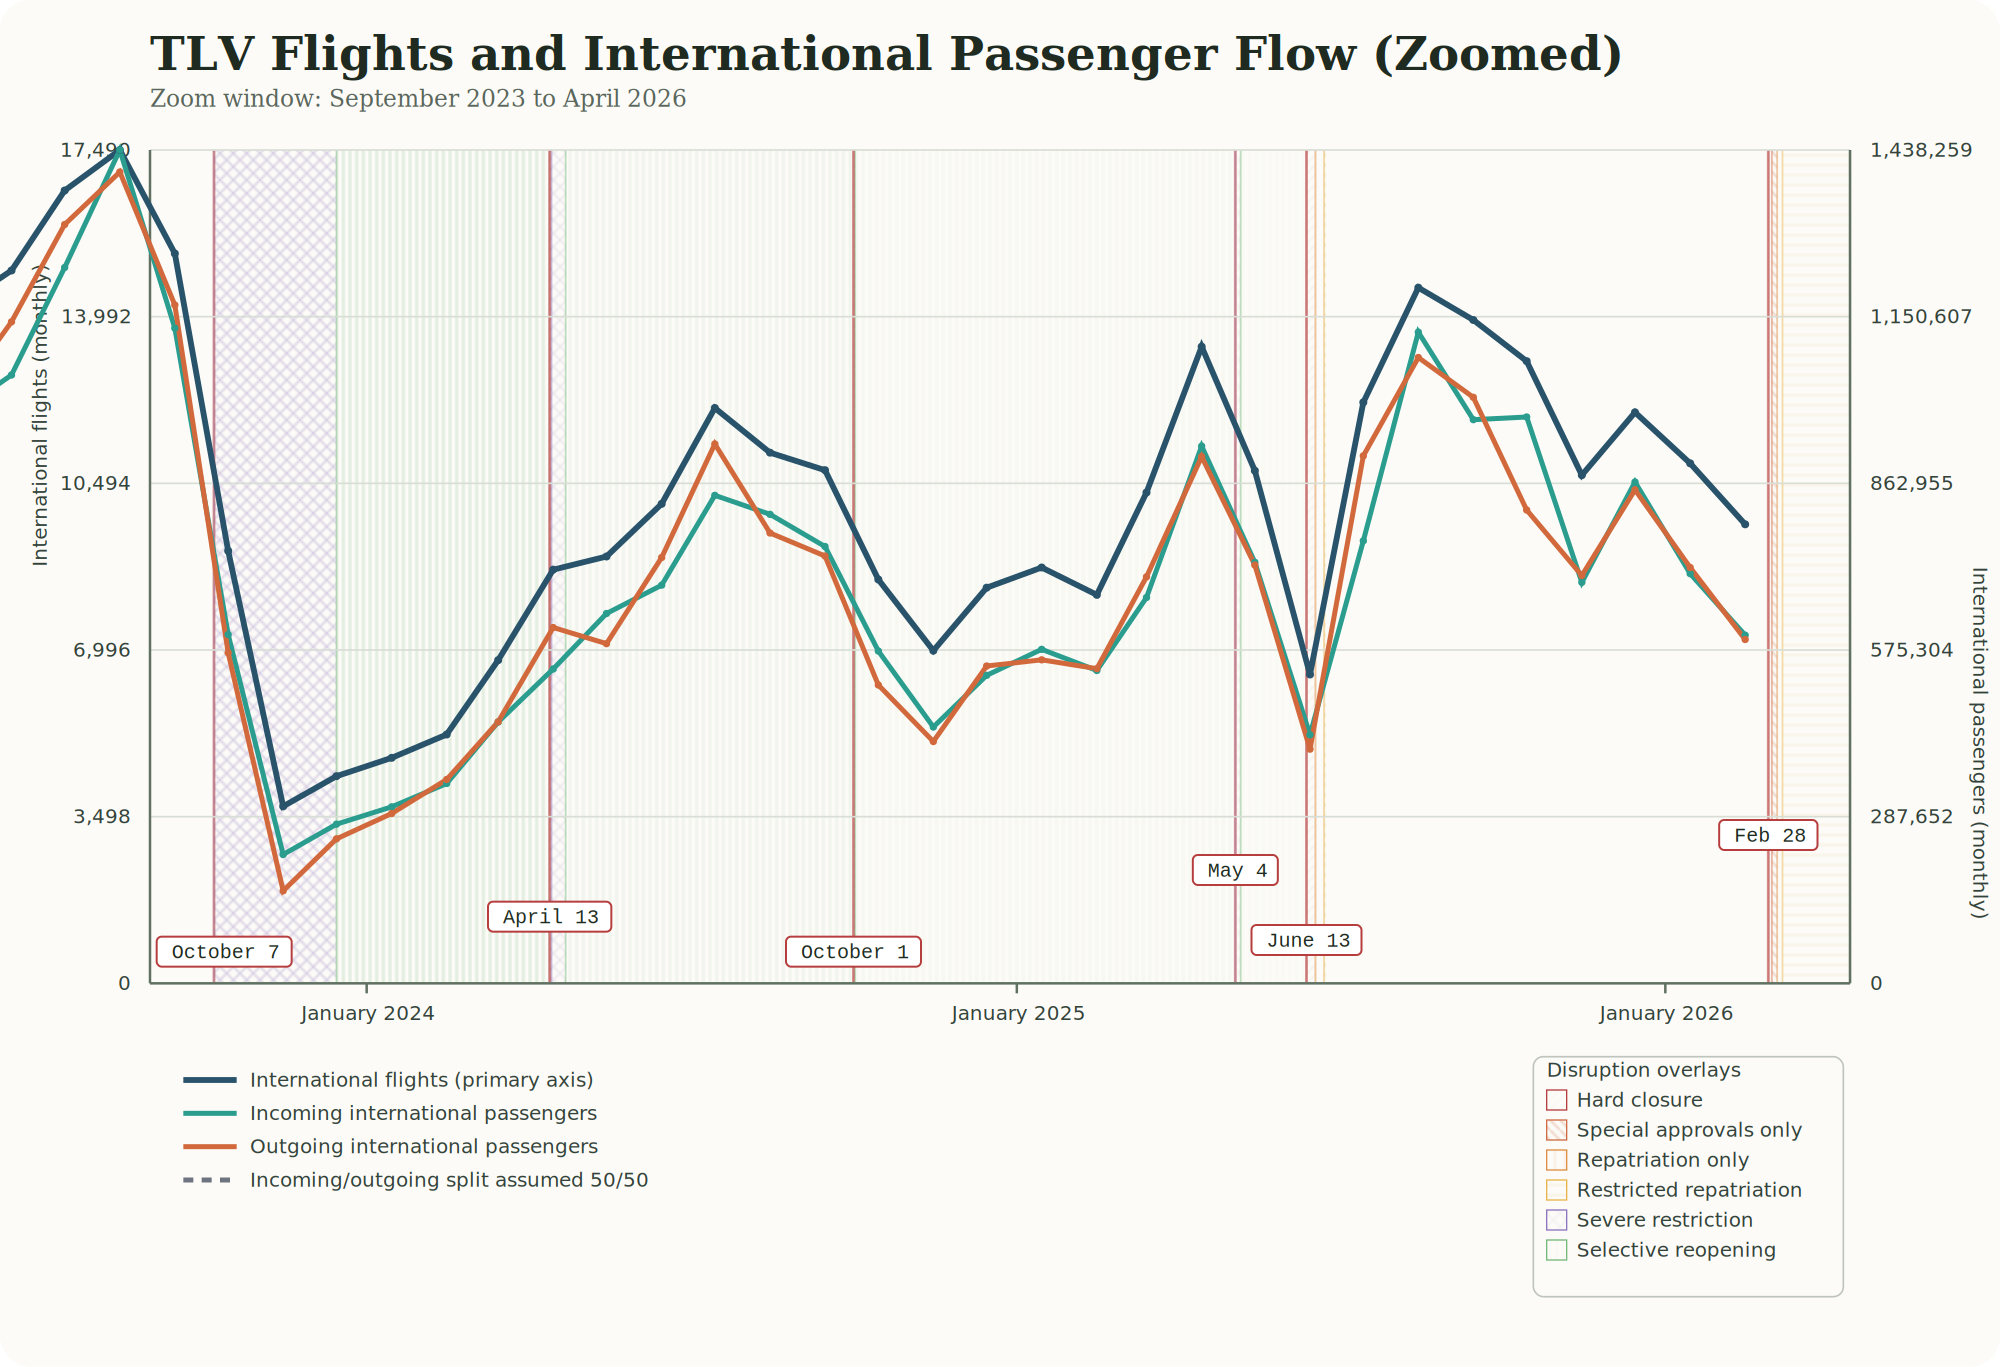
Chart 1: Monthly International Flights and Passengers
The following chart shows:
Total count of international flights per month (incoming + outgoing) – on the primary axis
Counts of incoming and outgoing international passengers – on the secondary axis
Disruption overlays for closure/restriction periods
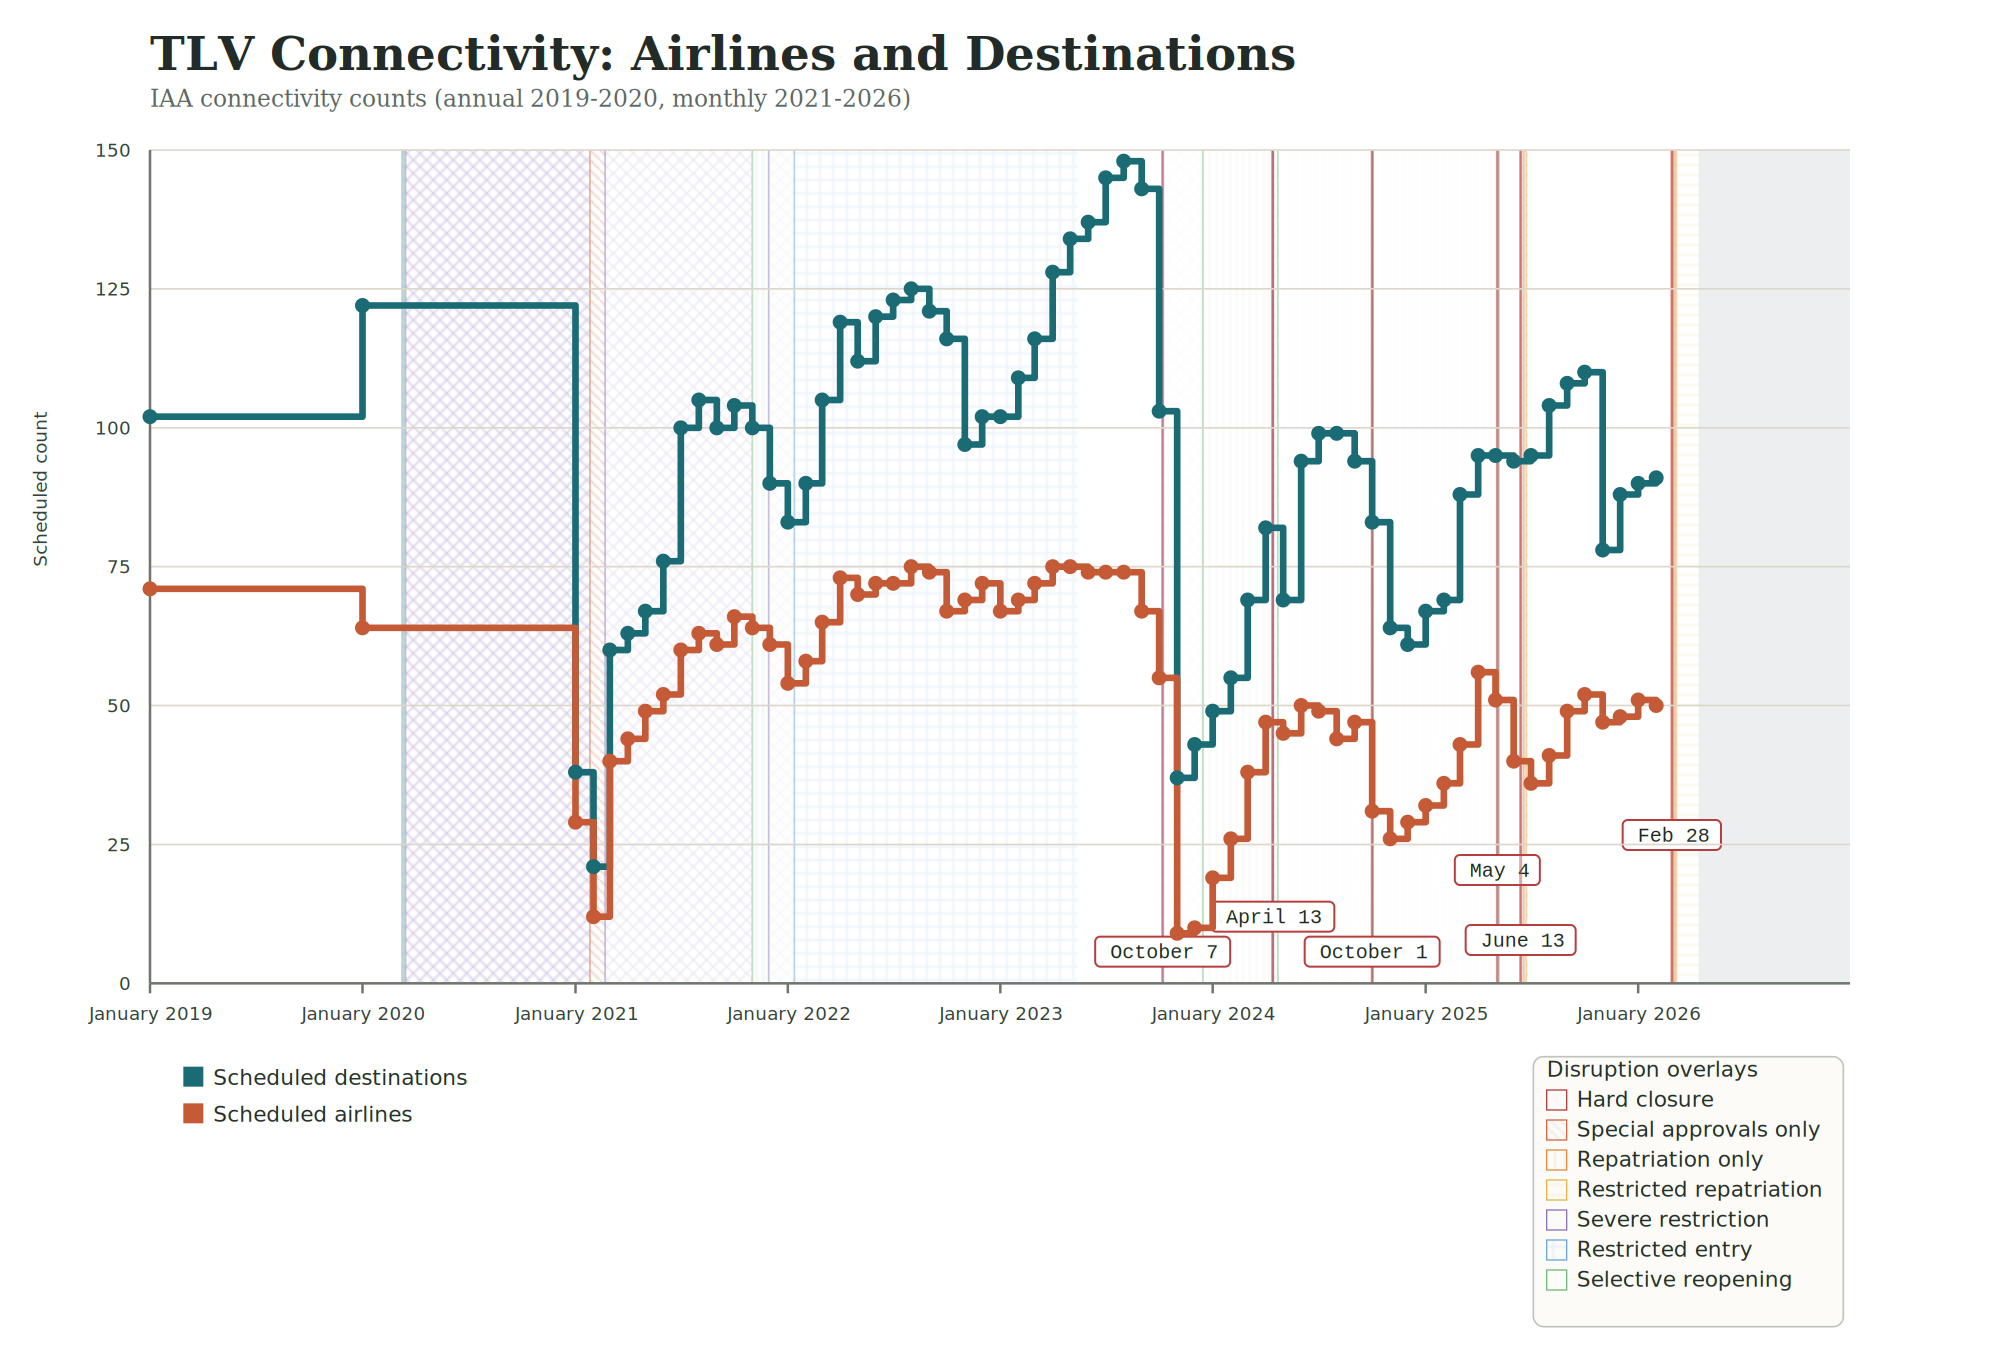
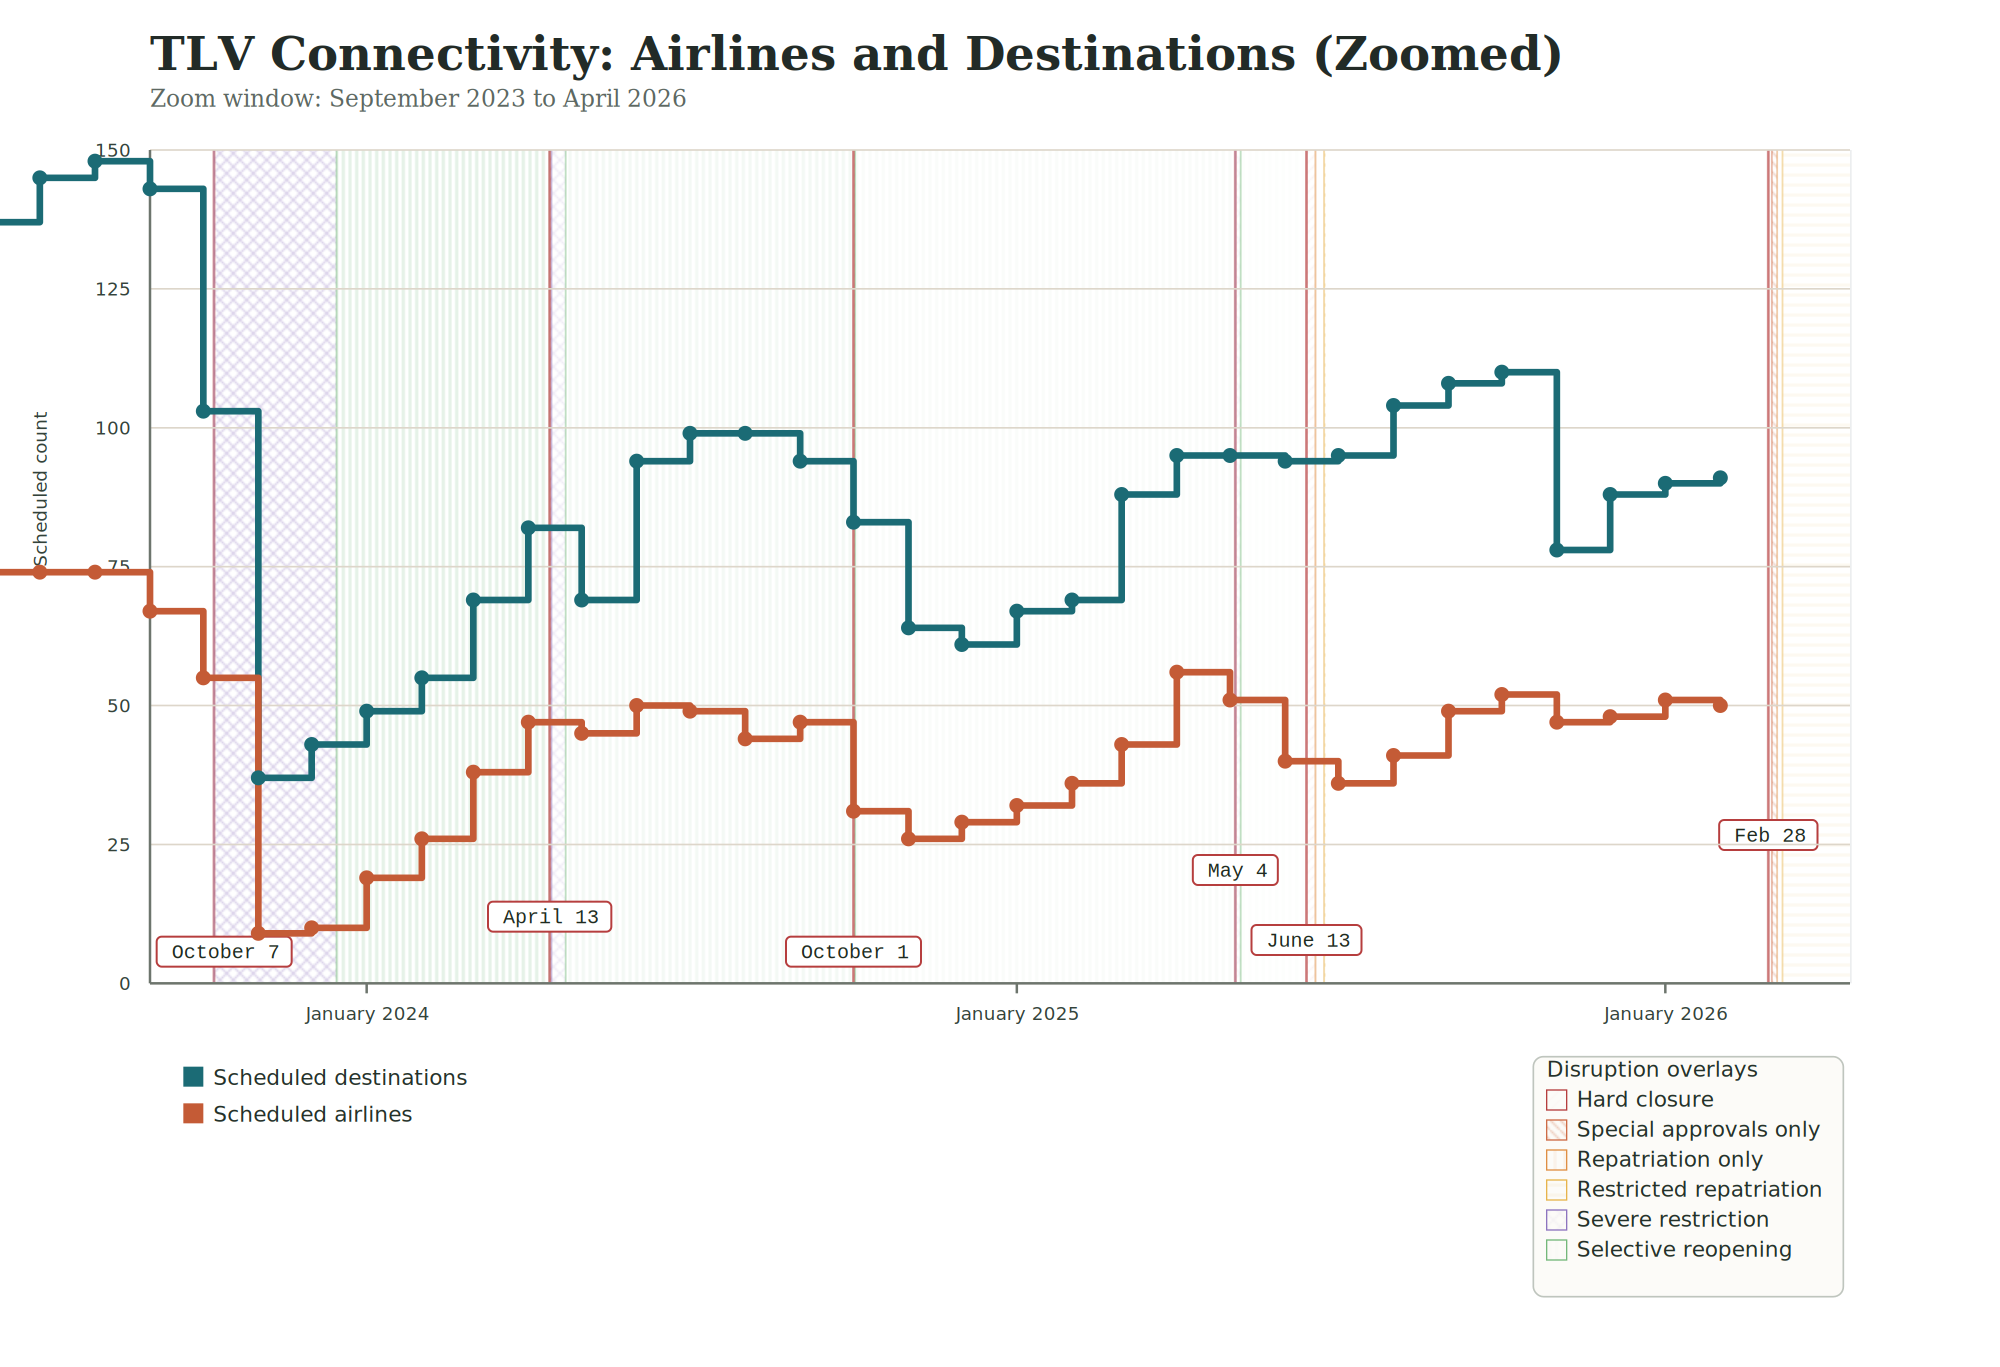
Chart 2: Scheduled Airlines and Destinations
How many airlines operated to and from TLV / LLBG (Ben Gurion Airport)? How many destinations are served by scheduled flights?
The following chart shows:
Airlines which had scheduled flights (annual counts in 2019 and 2020, then monthly)
Scheduled destinations (annual counts for 2019 and 2020, then monthly)
Airspace restrictions and travel restrictions overlaid
Caveat: The IAA reports include “OTHERS” rows in both airlines and destinations tables, so the actual number of airlines and destinations may be higher than shown in the chart.
The term “vibe coding” was coined by Andrej Karpathy in February 2025; Merriam-Webster listed it as “slang & trending” in March 2025; and Collins picked it as Word of the Year for 2025 (link, link, link).
Back then, in early 2025, it was a more-or-less derisive term, depending on who used it. It came with a strong assumption of serious limitations, criticisms about security flaws, and the idea that “it’s for beginners / non-coders”, not for experienced developers.
But now, two and a half months into 2026, the data shows the term’s usage is still growing. The tools that rode a wave of hype related to vibe coding in 2025 did not all survive the hype cycle. But the broader behavior of using coding agents is becoming more entrenched, and the term “vibe coding” is still in active use in early 2026.
Quick caveat: This post is based on Google Trends but Google Trends gives relative values (0-100), not absolute search volume. So we see “how interest moved” within each trend, we cannot compare directly trends between one another. Even search volume in turn, is only a proxy for interest, not a direct usage meter.
Two peaks in 2025, then a higher 2026 level
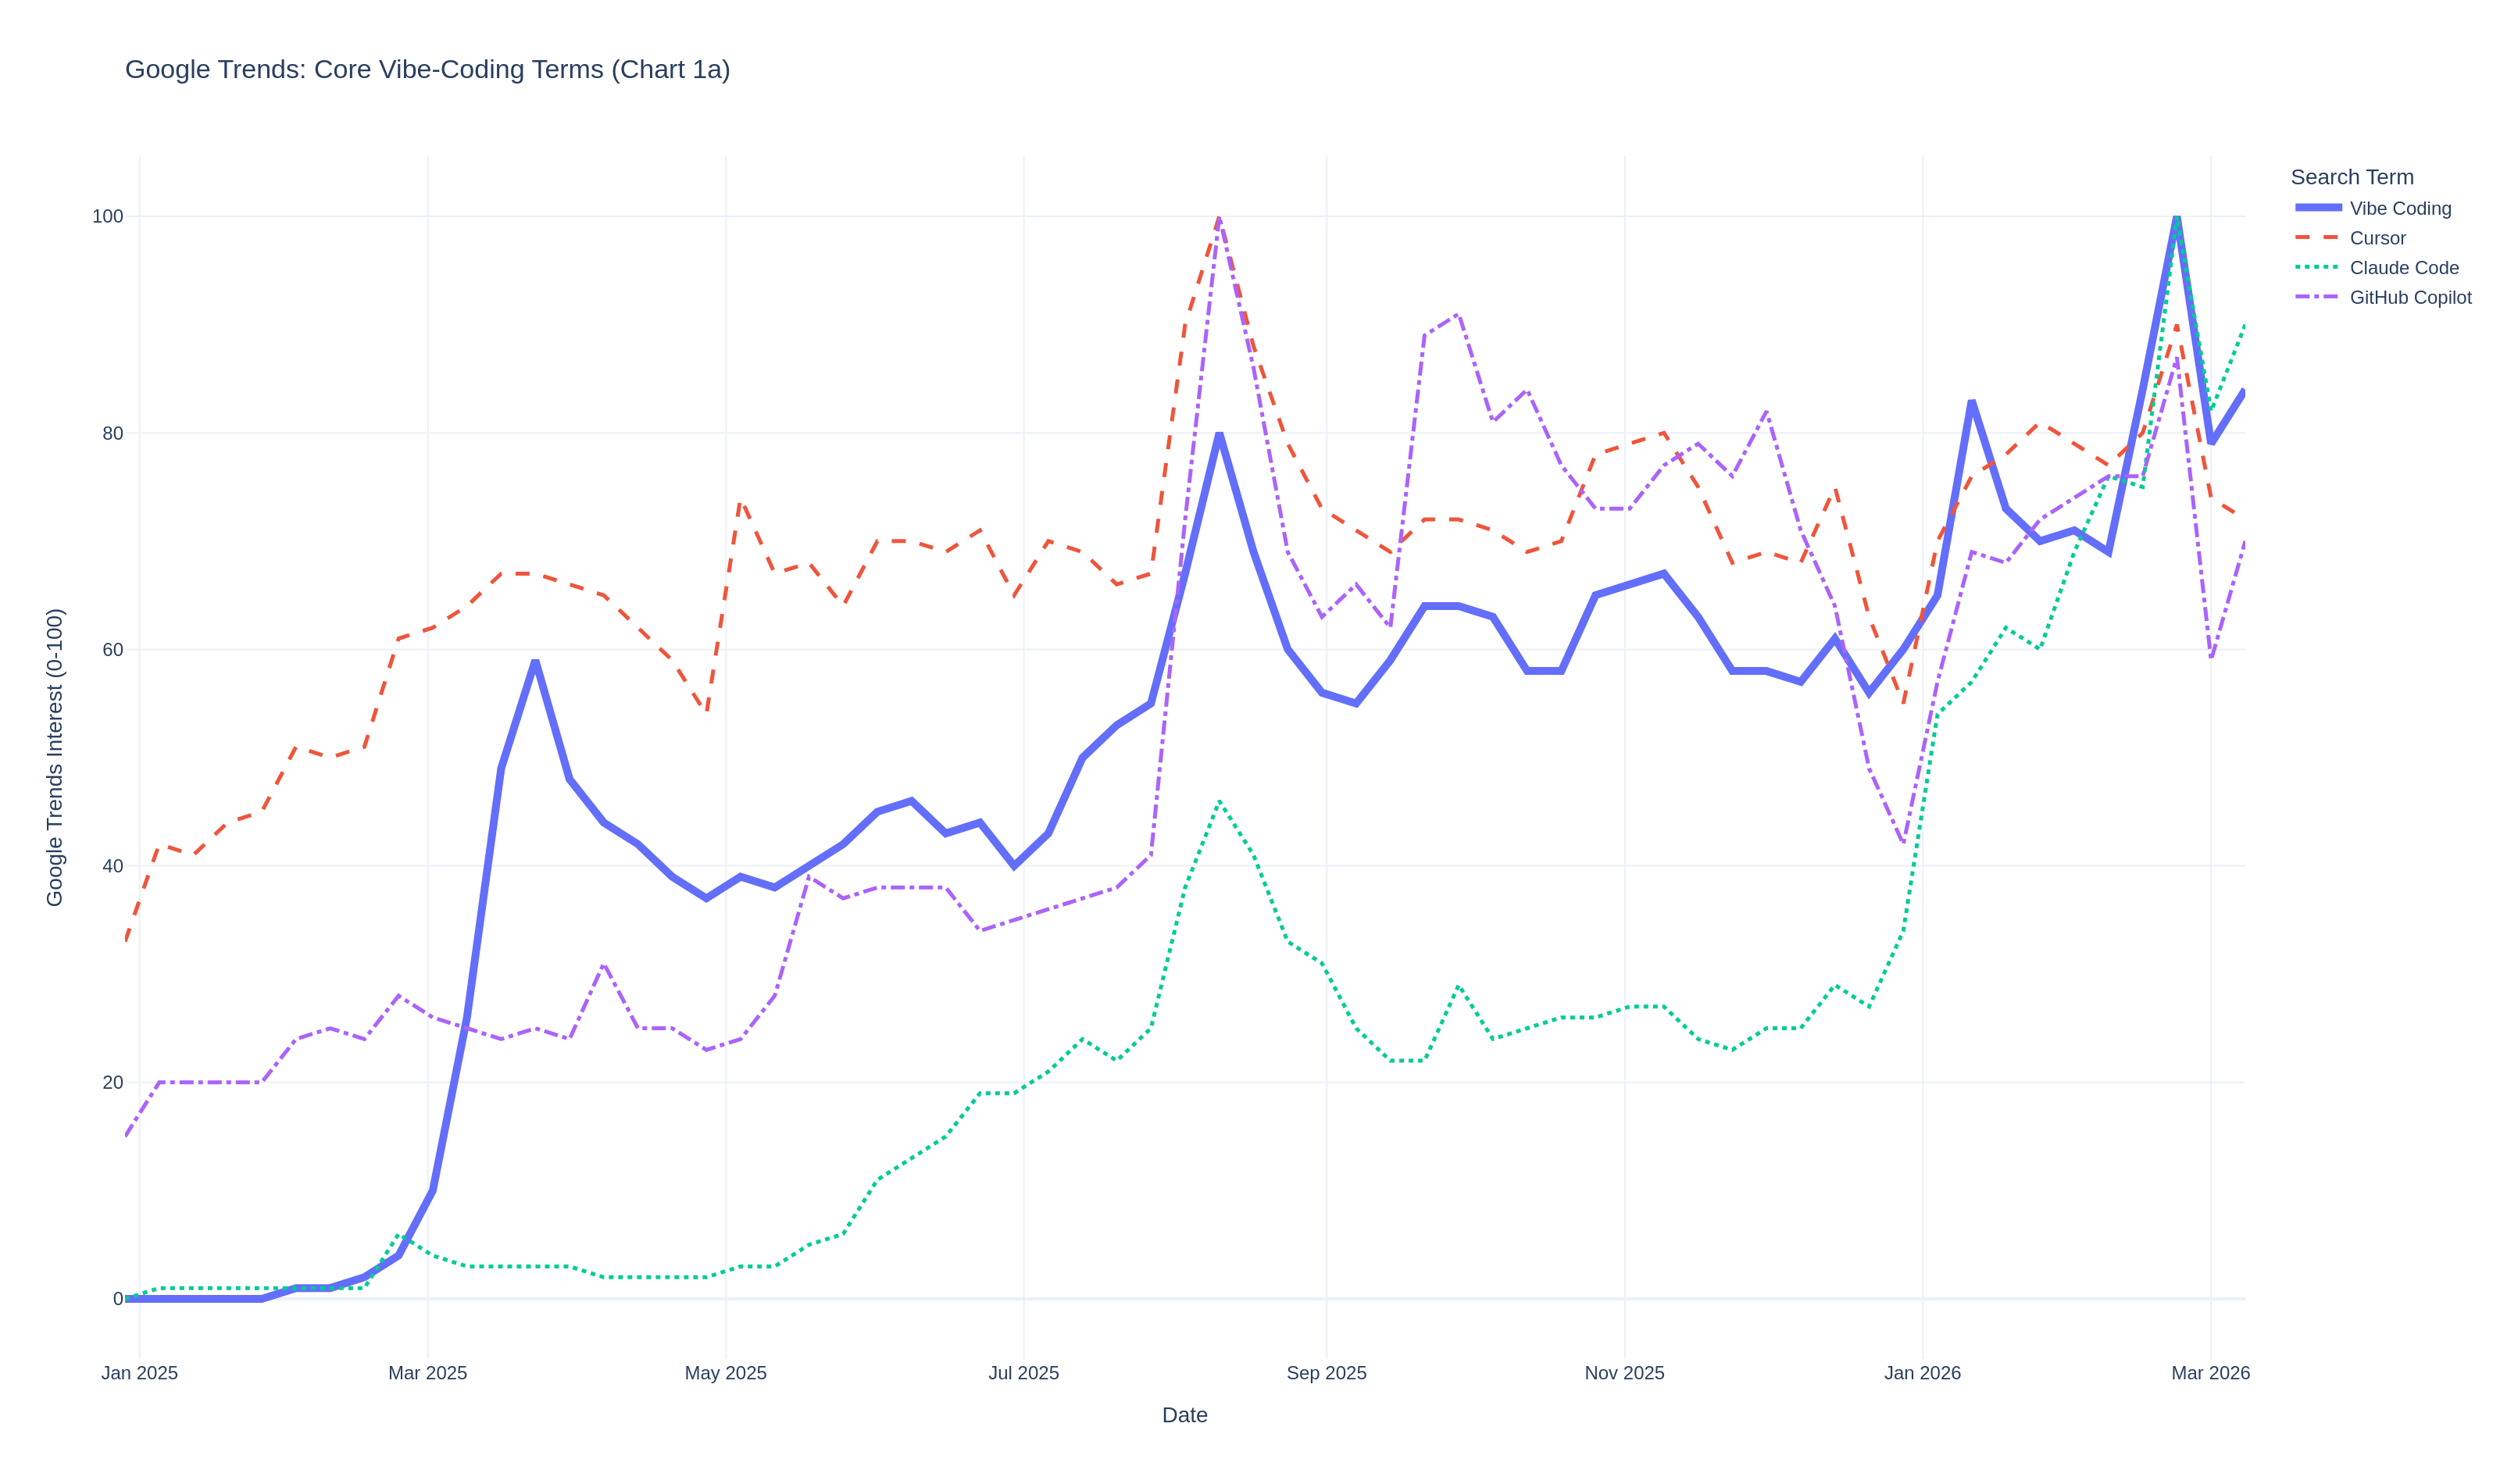
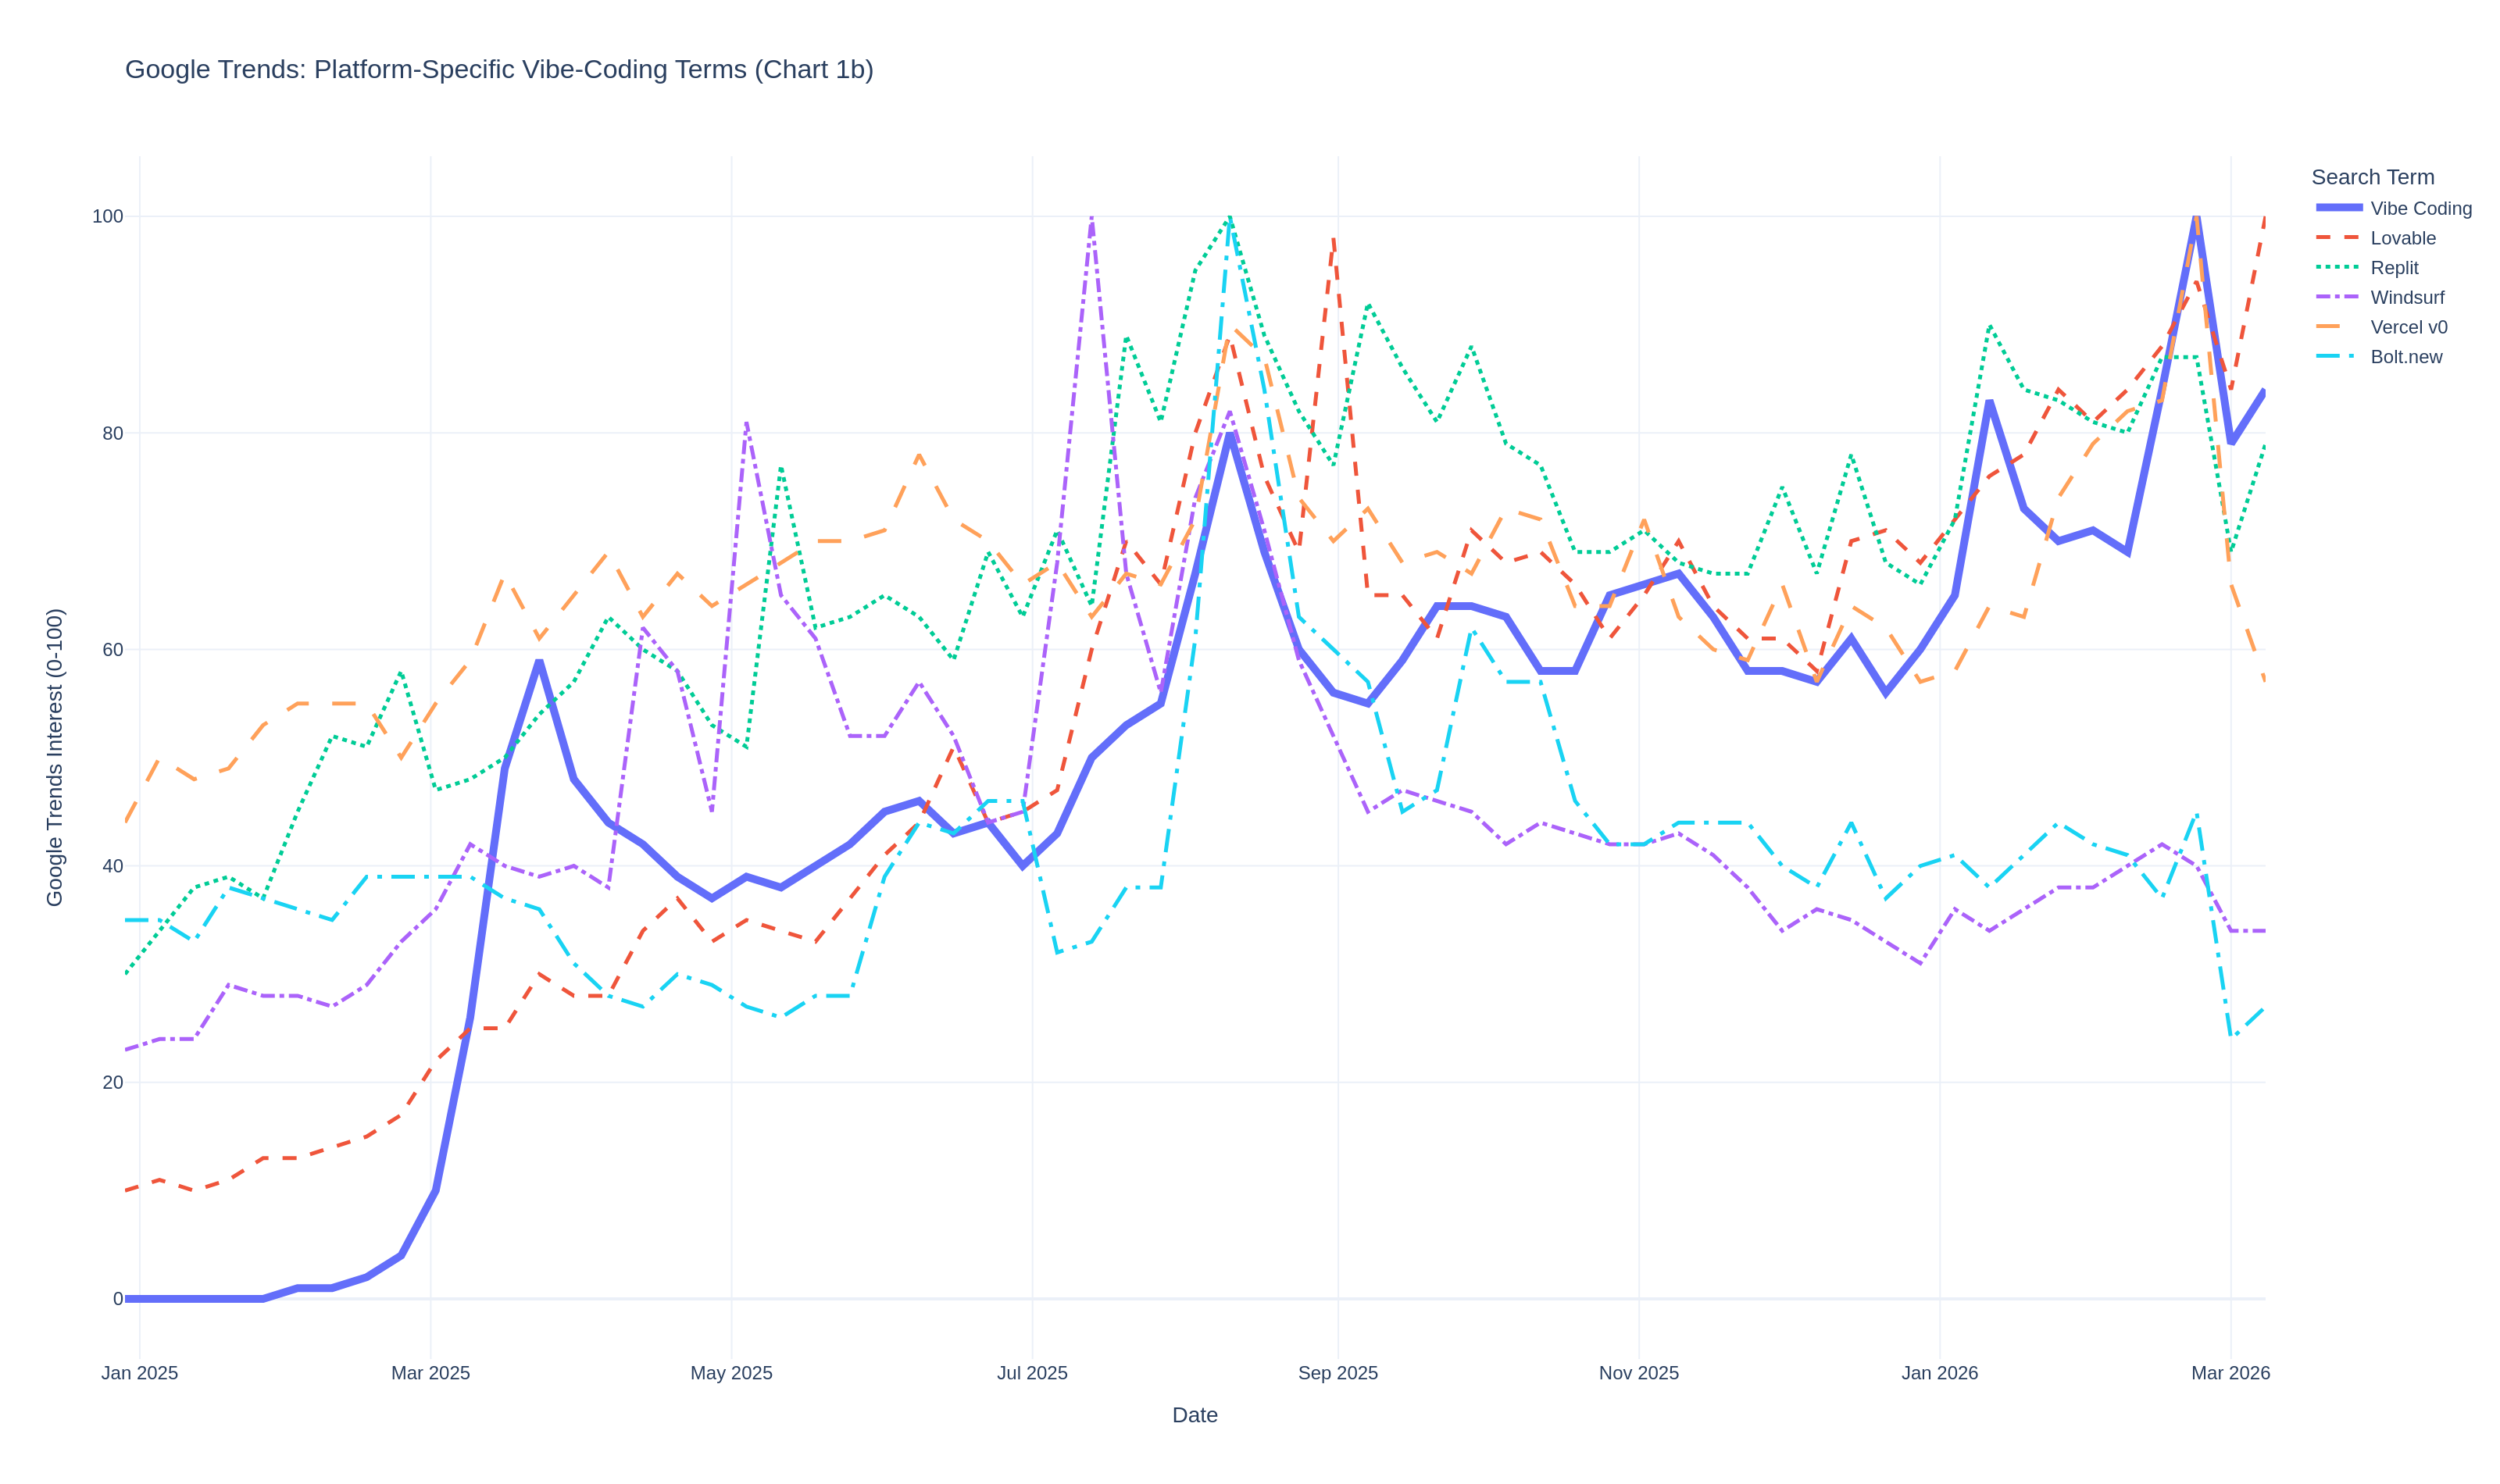
From Chart 1a/1b, the “vibe coding” query shows two clear peaks in 2025:
Spring 2025 (first real breakout, around late March / early April)
August 2025 (a second, larger wave, from a summer baseline around the 40s to a weekly peak near 80, then a slight cooldown)
In the last two and a half months (January to mid-March 2026), there looks to be a continued expansion: we see 83 in mid-January and 100 in late February, and March remains elevated.
A cleaner way to summarize the magnitude: from the March 23, 2025 local high (59) to the February-March 2026 average (about 82), the level is up by roughly 40%.
Claude Code’s rise is the most obvious late-period acceleration in this set (link). GitHub Copilot looks more mature and flatter by comparison, while attention shifts toward newer “agentic coding” labels and tools. One plausible context point is OpenAI’s Codex relaunch/push, which may have redistributed mindshare across names and workflows (link).
Also, this chart is intentionally selective. It does not include Google’s coding tools, for example.
The “platform wave” look is pretty clear: a broad lift into August 2025, then separation.
Lovable, Replit, and Vercel v0 hold up better afterward (with Lovable and v0 still very visible in later points) (link, link, link).
Windsurf and Bolt.new fade relative to their peaks in this specific search slice (link, link).
Why might that happen? Usually it’s a mix: category crowding, feature convergence, and users consolidating around fewer default tools as “AI coding” becomes normal rather than novel.
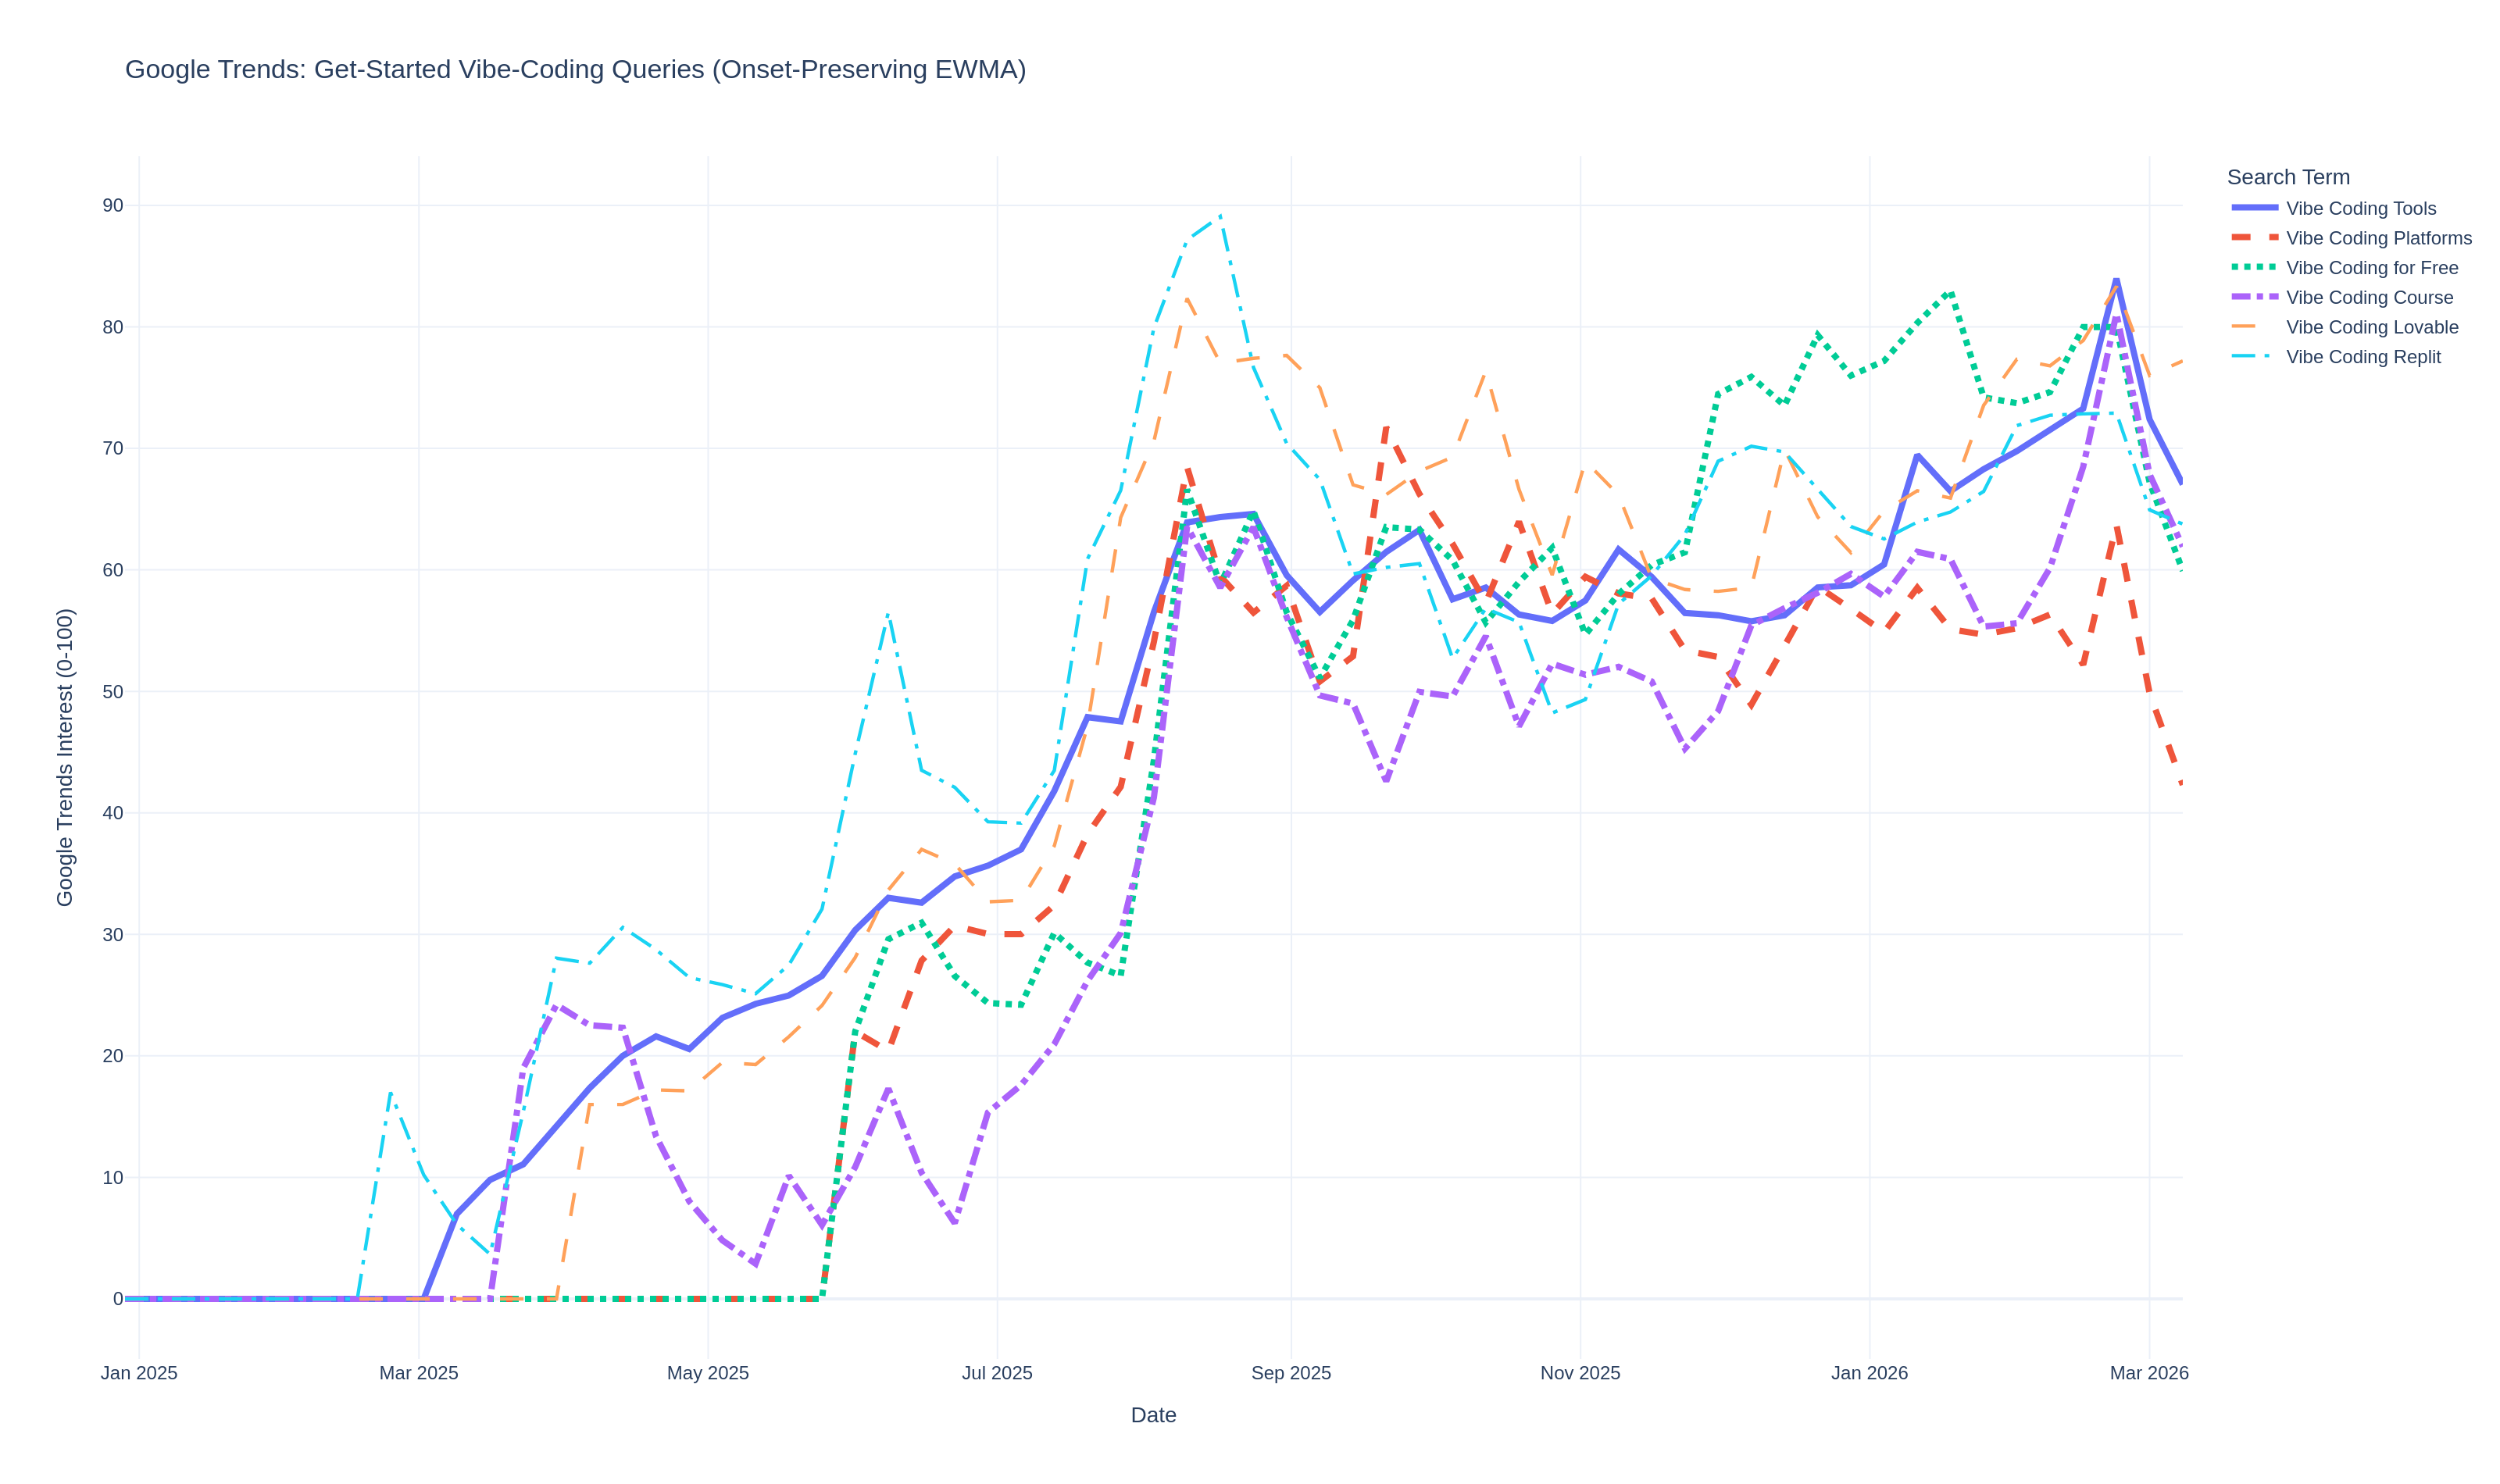
Chart 2: “How do I get started?” query intent
For this chart I filtered out terms that repeatedly dropped to zero in the second half of 2025 and used onset-preserving smoothing, so we keep direction without overreacting to one weekly bucket.
The key read is that generic “vibe coding” how-to intent does not explode upward on its own. Instead, intent fragments into tool-specific behavior: Claude workflows, Cursor workflows, Replit workflows, and so on.
Conclusions
My initial expectation was wrong. The term has not disappeared after 2025. It is still in active use in early 2026, and the broader behavior is of course even more entrenched.
“Vibe coding” still means “obtaining code (for a web site, a web app, any piece of software) through prompts”, but the assumptions of hard limitations, security flaws, and “only for beginners or non-coders” are totally passé, in a world where coding agents are becoming standard developer tools.
Data and method notes
Data source: Google Trends weekly series, Jan 1, 2025 to Mar 8, 2026 (link).
Important: this is relative index data, not absolute volumes.
Charts are from local CSV pulls and custom Plotly PNG exports.
Before it was called World War One, WWI was called in French “la der des ders”, in English “The War To End All Wars”.
Here in Israel, there is still a prevalent thought that another road, another lane, another interchange or another tunnel will “put an end to all congestion (forever)”. Road 6 was supposed to be the ultimate solution for the whole country: “The Road to End All Congestion”. Instead, apart from being an eyesore and a terrible environmental scar, it is itself congested every day: it turns out, to no serious person’s surprise, that by leading people to believe they can reside wherever they want and rely on a fast commute on Road 6 to wherever they need to be for work, to visit family or for entertainment, you create the conditions for no one to be able to do that.
Well, I’m starting to see a parallel here with Israel’s wars. Each one was supposed to be the end to Hamas aggression from Gaza, to Hezbollah’s rockets and threat at the northern border, to terror in the West Bank, to Iran’s ballistic missile threat… and then we need another one to achieve the same goal again – doesn’t that sound familiar?
I wish the prospects for the future of regional geopolitics were more like building high-speed train lines, mass transit and livable cities and less like building Road 6.
To be honest, in terms of transportation, the transition is not complete but I can see high levels of the technocratic state have understood the need for proper mass transit and livable cities. So now we need to send Netanyahu home and have a new government which tasks itself with bringing us a sustainable future.
Elon Musk has been so wrong about so many things for so long… But I want to focus on the Second Generation Tesla Roadster.
Tesla asked for serious money for the second-generation Roadster: about $50,000 for a regular reservation, and $250,000 upfront for the Founders Series. Just the Founders batch was capped at 1,000 people, so that alone is a lot of customer cash tied up, and Tesla has never really published a clear total for all reservations. By late 2025, several well-known cases said getting a refund was more painful than expected, with no easy one-click cancel, lots of follow-ups, and unclear timelines for when money would actually show up. So after years of waiting, some buyers ended up stuck not just with delays, but with a refund process that felt messy and unpredictable.
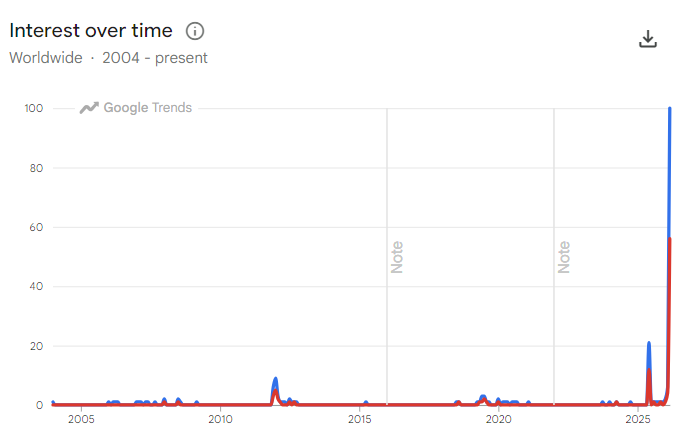
I was thinking overnight – I wouldn’t be surprised if the searches on Google for “Strait of Hormuz” peaked every now and then when the situation in the area gets tense. Most of the time, no one really knows or cares about what the Strait of Hormuz is. But I wasn’t ready for such a Google trend:
What happened in January 2012?
In January 2012, tensions spiked after Iran threatened to close the Strait of Hormuz in response to new U.S./EU oil sanctions and the U.S. Navy signaled it would keep the waterway open.
What happened in July 2019?
In July 2019, tensions surged again during the tanker crisis, especially after Iran seized the British-flagged Stena Impero following earlier tanker seizures and U.S.-Iran military incidents.
Obviously, June 2025 and … now, March 2026…
Suddenly everyone needs to know what the Strait of Hormuz is!
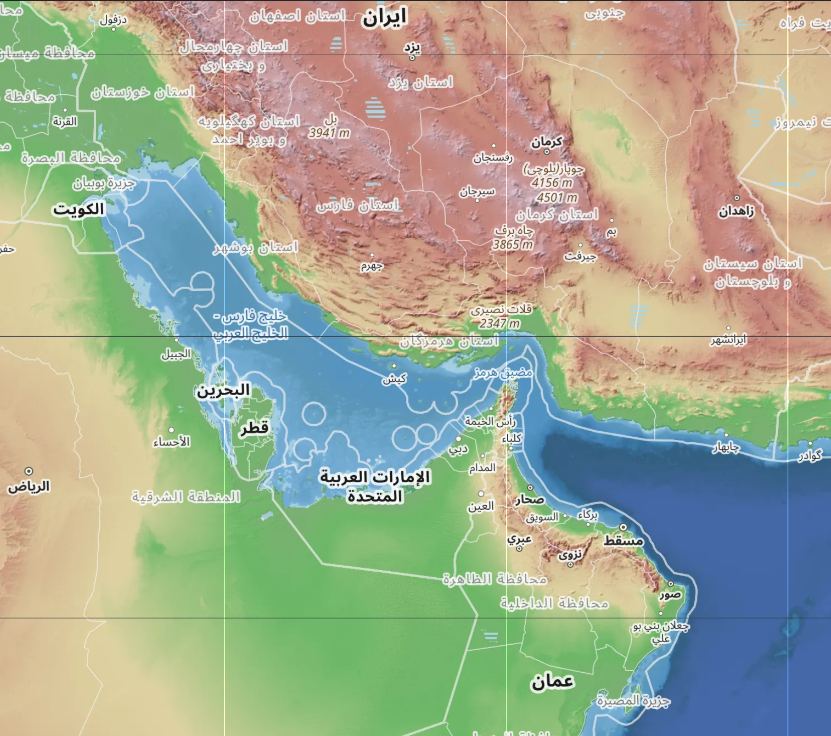
Even on a map in Arabic characters, you can find it…
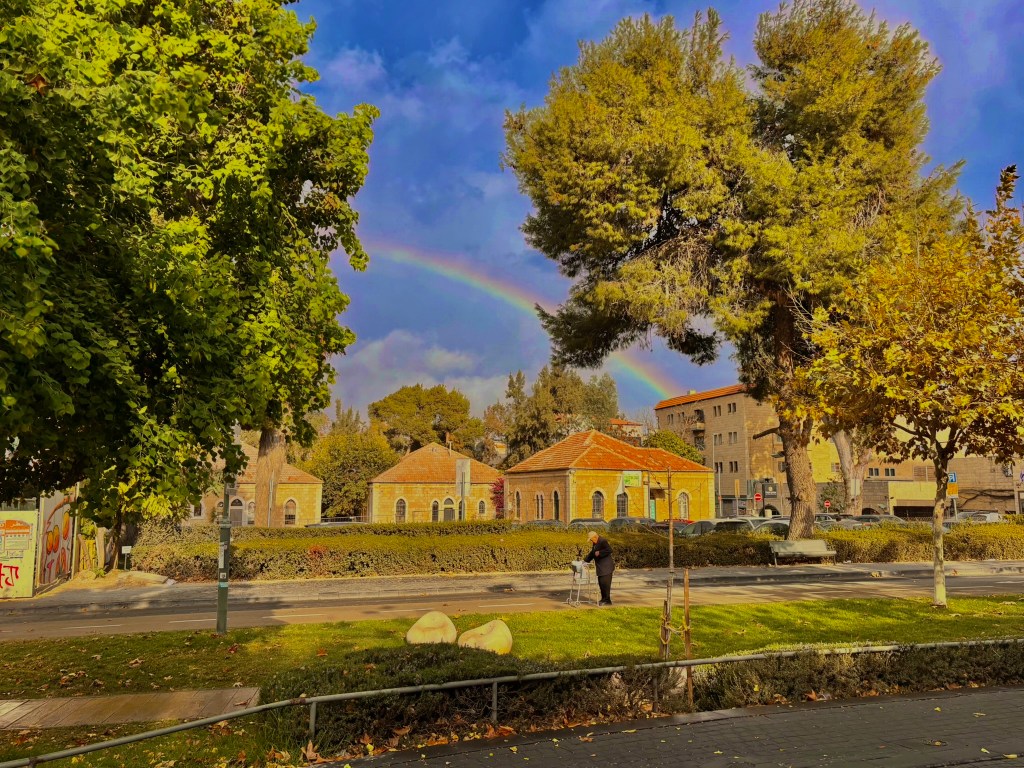
I might have applied quite heavily the filter (increased saturation, etc.) but only in order to be truthful to the sensation. Photo taken November 14, 2025 at 8:23 AM, local time.
In the previous rambling, Randomness in LLMs, preamble 1, I tried to illustrate how the LLMs I’m familiar with inherently use randomness to generate their answers and as such do effortlessly something that we humans are not very good at – at least I’m terrible at playing the categories game, or at coming up with a “random” recipe choice.
I would like to illustrate now, how this can come into play in something serious. I’m quite fascinated by the Shapira Fragments, a.k.a. The Valediction of Moses, and I did the following experiment:
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments are likely authentic, as their linguistic patterns and orthography resemble pre-exilic Hebrew rather than the later Biblical form known in the 19th century. Such features would have been almost impossible for a forger of that era to reproduce accurately, given the state of Semitic philology at the time. Moreover, their thematic differences from canonical Deuteronomy suggest an independent source tradition rather than a derivative imitation.
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments are almost certainly forgeries, as their sudden appearance without archaeological context and their convenient alignment with Shapira’s commercial interests raise clear suspicions. The leather strips reportedly disintegrated conveniently soon after examination, preventing any modern testing. Moreover, the linguistic oddities once taken as archaic are more plausibly explained as mistakes by a 19th-century imitator unfamiliar with genuine early Hebrew usage.
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments are likely authentic, since their linguistic and orthographic features anticipate discoveries like the Dead Sea Scrolls by decades. These details, unknown to scholars in Shapira’s time, suggest the text preserves a genuinely ancient stage of Hebrew. If forged, it would require an improbable level of foresight and philological knowledge for the 1880s.
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments are almost certainly forgeries, produced in a period rife with biblical antiquities frauds. Their script shows inconsistencies unlike any verified Iron Age Hebrew inscriptions. Combined with Shapira’s prior involvement in fake Moabite artifacts, the balance of evidence strongly points to deliberate fabrication.
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments may well be authentic, as their linguistic and stylistic traits align with an early stratum of Hebrew unattested until the Dead Sea Scrolls were discovered. Such accuracy in ancient orthography and syntax would have been beyond the reach of any 19th-century forger. Their differences from canonical Deuteronomy suggest a genuine, older version of the text rather than a modern imitation.
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments are almost certainly inauthentic, as no physical trace of them remains for scientific verification. Their sudden emergence through a dealer with a history of dubious artifacts undermines their credibility. Furthermore, the text’s deviations from known ancient Hebrew forms are more consistent with creative invention than with genuine antiquity.
I said:
Make the point for or against the authenticity – but only one of them – of the shapira fragments in three sentences
ChatGPT said:
The Shapira fragments may be authentic, since their script and linguistic forms anticipate patterns confirmed only decades later by genuine Dead Sea Scroll discoveries. This suggests knowledge of ancient Hebrew unavailable to any 19th-century forger. Their variant version of Deuteronomy therefore plausibly represents an early, pre-canonical stage of the biblical text.
So here, ChatGPT argued four times for authenticity and three times against it. There is no reasoning: the model starts with one word, then the next – as we saw in the previous post – and ends up with a randomly generated but consistent thought.
The reason I experimented with this, is that I wonder what the probability distribution in the conceptual domain is. Can we trust that if the model argues 57% for authenticity vs. 43% against it, this means the posterior probability of the hypothesis that the fragments are authentic is 57%? Or is there a language bias, leading to it being “easier” to argue one way or another?
Besides, a single LLM-generated sequence of tokens is only one stage of actual “reasoning” – or cognitive production of results. My question is: will reasoning require exhaustive search through options (here – authenticity and inauthenticity), or stochastic search, where more likely options are sampled more often?